NVIDIA has expanded its NVLink Fusion programme with NVHBM, a custom high-bandwidth memory base die that partners can use instead of the standard base die shipped with commodity HBM4E stacks. NVIDIA NVHBM memory moves the memory controller off the compute die and into the 3D-stacked HBM package itself, and NVIDIA says the result is more bandwidth, lower power draw and more usable die area for compute logic.
How NVIDIA NVHBM memory works
Standard HBM puts the memory controller on the compute die, the GPU or XPU doing the actual processing, which means silicon that could otherwise hold compute logic is spent on memory I/O instead. NVHBM relocates that controller into the HBM stack’s base die, the same die that already sits under the DRAM layers and handles routing between the stack and the host chip. NVIDIA says this frees up to 25% more usable compute die area on the processor, since the controller no longer competes with compute logic for space.
The change is paired with a custom physical interface, or PHY, that is narrower than the standard JEDEC HBM4E interface. According to TechPowerUp’s coverage of NVIDIA’s announcement, the redesigned PHY cuts I/O area by up to 67% compared with JEDEC HBM4E, and the narrower interface frees up to 80% more usable interposer silicon. That matters for anyone trying to fit several HBM stacks alongside a large compute die on the same package, since a wider commodity interface eats into the interposer routing available for everything else.
The vendor’s bandwidth and power claims
NVIDIA is claiming up to 30% higher memory bandwidth and 15% lower HBM power consumption than standard HBM4E. Those are NVIDIA’s own figures for a memory technology that has not shipped in any named product yet, not results from an independent benchmark, so they describe what the design is meant to achieve rather than what has been measured in a running system.
NVIDIA says NVHBM was designed and validated with unnamed “leading memory vendors”, which it frames as a faster route to market than a custom silicon partner building an HBM implementation from scratch. Full technical detail on the design is in NVIDIA’s own blog post.
Only for NVLink Fusion’s custom silicon partners
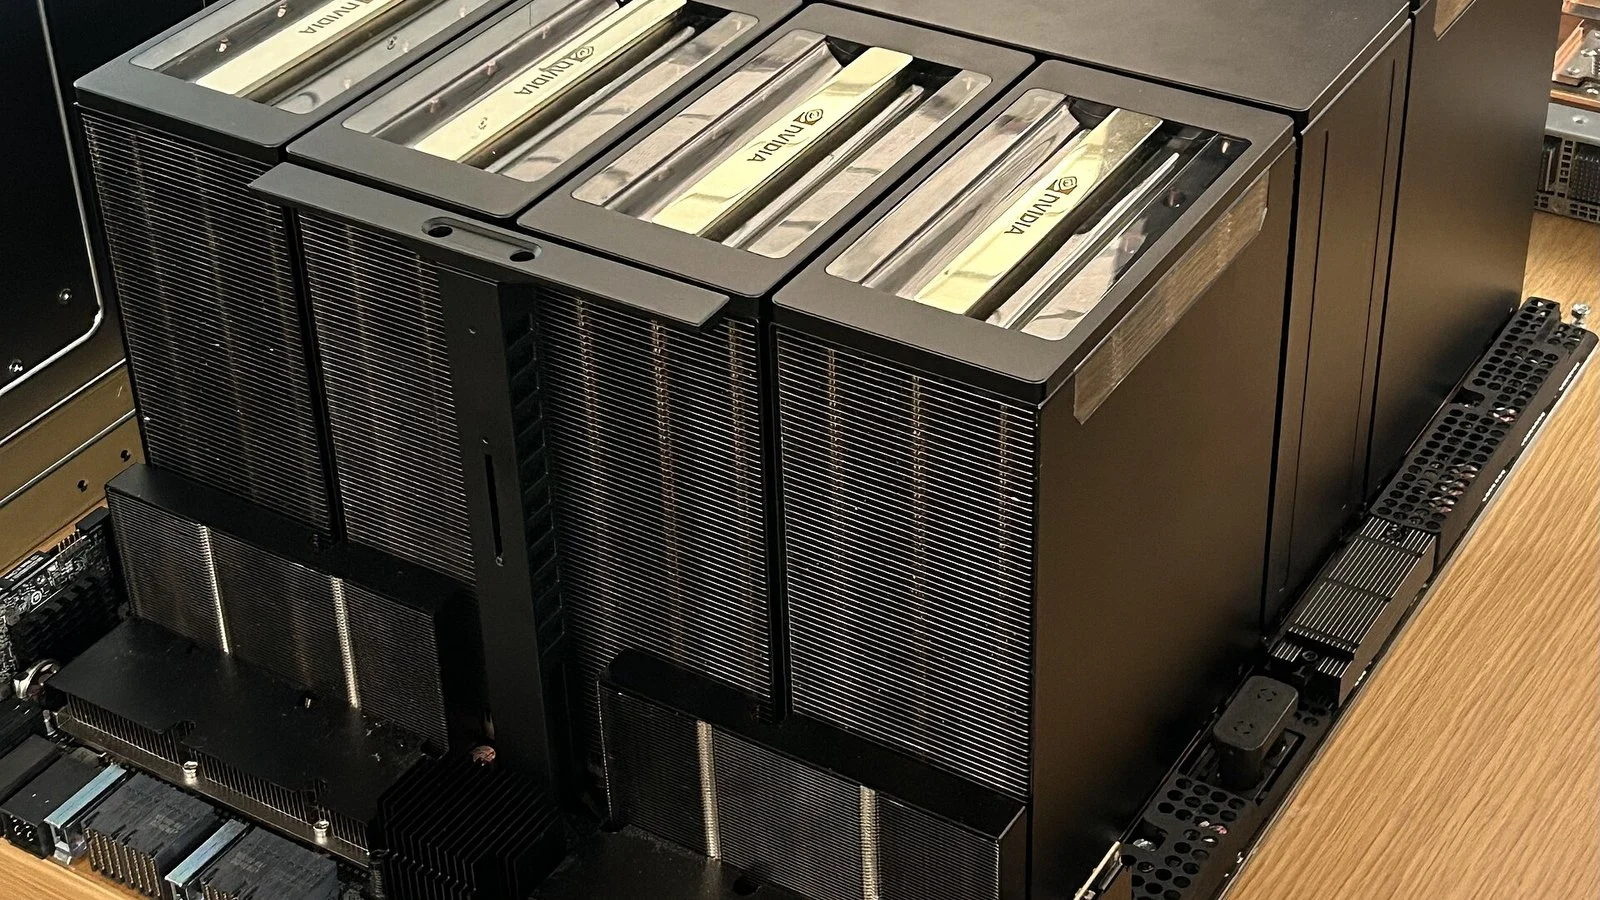
NVHBM is not a replacement for commodity HBM4E, and it is not going on general sale. NVIDIA is offering it exclusively to the custom silicon partners building chips through NVLink Fusion, the programme that lets third-party processors join NVIDIA’s NVLink scale-up domain, the same interconnect fabric used inside rack-scale systems like the Vera Rubin NVL72. That restriction is the point: NVIDIA gets to define the memory interface for every accelerator that joins its ecosystem, commodity or custom, rather than leaving custom silicon vendors to spec their own.
The push mirrors a broader industry scramble to squeeze more bandwidth and efficiency out of AI infrastructure, a scramble that also has Intel detailing its own agentic AI chip push with Diamond Rapids and Crescent Island.
NVIDIA has not named which NVLink Fusion partners plan to use NVHBM in a shipping chip, or when the first one might tape out. Worth watching for is whichever custom silicon vendor announces the first product built on it, since that will be the first real test of NVIDIA’s bandwidth and power figures outside a slide deck.
Image: Pokiiri via Wikimedia Commons, licensed under CC BY-SA 4.0.